Escaping the Monolith: Designing Scalable Multi-Agent Ecosystems in Agentforce
Picture a retail company that builds its first Agentforce support agent. The scope starts small and sensible: confirm who the customer is, answer a few common questions, and hand off anything messy to a human. It works well. Customers get fast answers, the support team stops drowning in repetitive tickets, and the project gets called a win in the next quarterly review.
Then someone in product marketing asks: can it also answer questions about our catalog? Sure, why not. Someone in operations asks: can it also let customers check order status, or cancel an order themselves? That seems reasonable too. Six months later, the same agent that used to greet customers and defer to a human is now expected to verify identity, search a product catalog, calculate shipping windows, initiate returns, check warehouse inventory, and escalate complex disputes, all inside one conversation, all inside one prompt.
This is the moment most Agentforce builds start to wobble. Not because the platform can't handle complexity, but because a single agent was never designed to carry all of it at once. This chapter walks through why that happens, what a better structure looks like, and how to build it without turning your architecture diagram into a spider's web of connections nobody can debug six months from now.
When a Simple Agent Stops Being Simple
Let's start with the agent most teams actually build first, because it's a genuinely good pattern. A baseline Agentforce service agent typically ships with three supporting jobs handled through sub-topics or lightweight sub-agents:
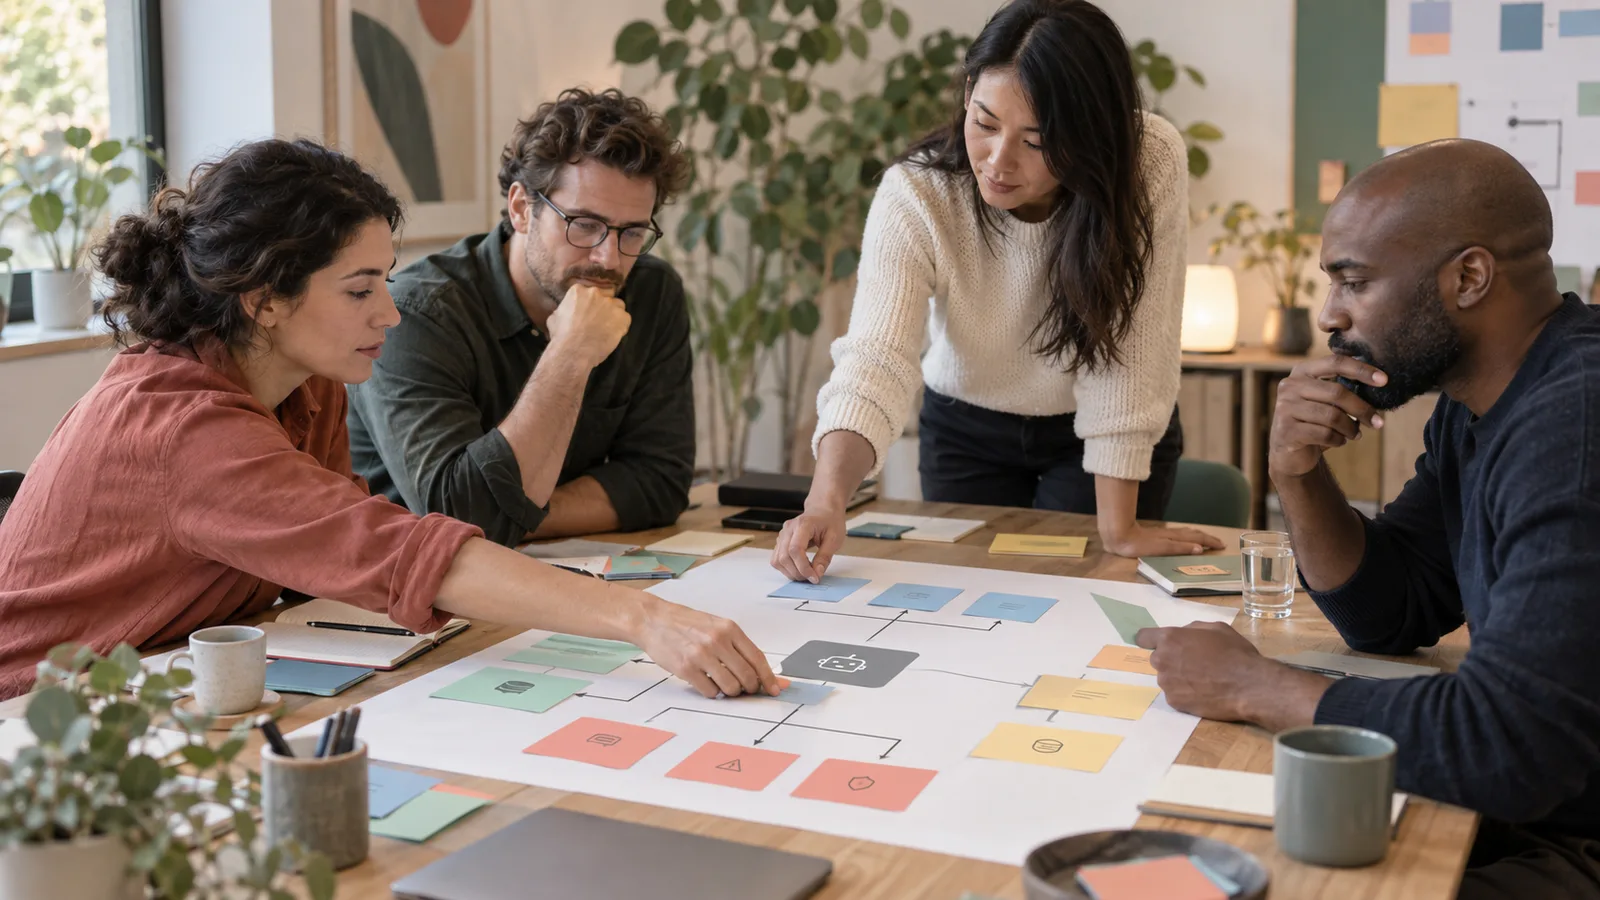
User confirmation:
verifying the person on the other end of the chat is who they say they are, usually by matching contact details or an authenticated session.
Off-topic handling:
politely redirecting questions the agent has no business answering, like requests for legal advice or unrelated product lines.
Escalation:
recognizing when a conversation needs a human, and handing it off cleanly with context intact.
This baseline is stable because it's narrow. The agent isn't trying to be an expert in anything; it's trying to be a competent gatekeeper. It confirms identity, filters noise, and knows when to get out of the way. Think of it as the front desk of a large office building: it doesn't need to know how every department works, it just needs to know where to send people.
The first real expansion usually goes well too. A team connects the agent to Data Cloud's vector search and grounds it in product documentation, so it can answer questions like "does this blender have a glass or plastic jug?" or "what's the warranty on this laptop model?" Because Data Cloud can pull structured and unstructured data, things like spec sheets, PDFs, and support articles, into a searchable index without dumping the entire catalog into the prompt, the agent gets smarter without getting heavier. At four sub-agents (identity, off-topic, escalation, and product knowledge), the system is still lean, still fast, and still easy for one person to maintain.
The trouble starts with the third expansion: transactional capability. Order creation, order updates, cancellations, inventory checks. These aren't simple lookups. They involve business rules, API schemas, validation logic, and connections to an Order Management System that has its own quirks and constraints. Once this gets bolted onto the same agent that's already handling identity checks, off-topic deflection, and product Q&A, you've built something that has to reason across four completely different domains inside a single context window, on every single turn of the conversation.
Here's what that actually looks like under the hood. Every instruction, every action definition, every API schema for every domain gets loaded into the same prompt space, whether or not it's relevant to the current question. Ask the agent what color a jacket comes in, and it's still carrying the full weight of order cancellation logic, inventory schemas, and escalation rules in its working memory. This is what we can call monolithic agent bloat: performance degradation caused by cramming multiple unrelated domain schemas and instructions into one context window, regardless of what the user actually asked.
Pause and inspect
What the monolith is carrying into every turn
The consequences show up in three predictable ways.
First, you hit context limits. Every large language model has a maximum amount of text it can hold in working memory at once. When your prompt is stuffed with instructions for four or five different jobs, there's less room left for actual conversation history. Customers who go back and forth for more than a few exchanges start to notice the agent "forgetting" what they said three messages ago, because older parts of the conversation get pushed out to make room for all that standing instruction weight.
Second, you get what we'll call the specialization gap. A reasoning engine juggling both "answer a simple FAQ" and "process a complex order cancellation with three validation steps" starts blurring the two. It might apply transactional caution to a basic question, asking for verification it doesn't need, or worse, it might rush through an actual order change with the same lightweight confidence it uses for FAQ answers. Accuracy drops in both directions.
Third, you get sequential bottlenecks and reliability risk. A single agent processing a transactional request has to reason through everything in one pass: confirm identity, interpret intent, select the right action, format the correct payload, call the external system, and then explain the result in plain language. If any one of those steps sits inside a bloated context, response latency stretches out, and the odds of a malformed action call go up. Multiply that across thousands of conversations, and you get a support agent that's slow on Tuesdays and unreliable on Fridays, without anyone being able to point to exactly why.
None of this is a knock on Agentforce. Atlas, the reasoning engine underneath Agentforce, is genuinely good at holding a conversation and figuring out what a customer wants. The problem is architectural, not technological. You're asking one agent to be a receptionist, a product expert, and a warehouse operator at the same time, and expecting it to be excellent at all three. It won't be. It'll be adequate at all three, which for a customer support experience is a real problem.

The Four-Tier Model: Breaking the Monolith Apart
The fix isn't to make the single agent smarter. It's to stop asking one agent to do everything. This is the core idea behind what we'll call the Four-Tier Agentic Specialization Model: a structure with a lean router at the top and three distinct categories of specialist underneath it.
Router:
the orchestrator that greets the customer, confirms identity, filters off-topic requests, and classifies intent.
Knowledge Specialist:
a sub-agent grounded in product and policy data, built to answer informational questions.
Transaction Specialist:
a sub-agent connected to backend systems like an Order Management System, built to execute real changes.
Escalation Manager:
a sub-agent (or in simpler builds, a topic) responsible for clean handoff to a human when the conversation needs one.
Here's the important shift in thinking: the router agent is no longer trying to know everything. It's trying to know just enough to send the conversation to the right place. Think of it like a hospital triage desk. The person at that desk doesn't perform surgery or read X-rays. They ask a few sharp questions and direct you to the right department. That's the entire job, and it's why triage desks move fast, even when the hospital behind them is enormously complex.
When a customer asks, "can I get a refund on the shoes I ordered last week," the router doesn't need product catalog knowledge or OMS schema details to handle that request well. It just needs to recognize the intent as transactional, confirm the customer's identity has already been verified, and route the conversation to the Order Specialist. That sub-agent, and only that sub-agent, carries the instructions and actions related to order changes. It has its own context window, its own action library, and its own prompt tuned specifically for one kind of work.
This is what we mean by context isolation: restricting each sub-agent's prompt space exclusively to the knowledge and actions relevant to its domain. The Knowledge Specialist doesn't carry order cancellation logic. The Order Specialist doesn't carry product spec sheets. Neither one is dragging around instructions it will never use on a given turn, which means the reasoning engine inside each sub-agent has more room to think clearly about the one job in front of it.
The practical result is a system that behaves less like one overworked employee and more like a well-run team. Specialized agents like an order specialist or a case specialist handle exactly what they're built for, without ever having to load or process instructions belonging to a different domain. Adding a new capability later, say a returns specialist for a new product line, means adding a new sub-agent to the roster. It doesn't mean touching the router's core logic or risking regressions in the product knowledge agent that's been working fine for a year.
It's worth being honest about the tradeoff here: multi-agent systems are more work to set up than a single agent. You're building more topics, more instructions, more test cases. But that upfront cost buys you something monolithic designs can't offer at scale, which is the ability to add business capability without every addition making the whole system slower and less predictable.
How Data and Identity Move Between Agents
Splitting an agent into pieces creates an obvious question: how does the system remember who the customer is, and what they've already told it, as the conversation moves from the router to a specialist and possibly back again?
The answer is session boundary passing: transferring authenticated identity variables between agents without asking the customer to repeat themselves. Once the router agent confirms who a customer is, typically by matching contact details, an order number, or a verified account session, it holds onto that verification as a session variable. Two of the most common variables passed forward are a validated Contact ID and a session or auth token confirming the identity check already happened.
When the router hands the conversation to the Order Specialist, it passes those variables along quietly, in the background. The customer never sees this handoff and never gets asked "can you confirm your account again" a second time. From the sub-agent's point of view, it receives a conversation that already comes with a verified identity attached, so it can skip straight to figuring out which order the customer means and what change they want made.
Picture this as a relay race. The router runs the first leg, identity verification, and instead of stopping the race to hand off the baton with a long explanation, it passes it in one smooth motion while both runners are already moving. The Order Specialist picks it up and keeps running, without ever needing to ask, "wait, who are you again?"
This matters for two reasons beyond convenience. First, customers find repeated identity checks frustrating, and every extra verification step is a chance for someone to abandon the conversation. Second, and more important from a security standpoint, it keeps the verification logic in one place. The router is the single point where identity gets checked and confirmed. Sub-agents trust that confirmation rather than re-implementing their own version of it, which means you're not maintaining five different identity-checking routines scattered across five different sub-agents, each one a potential gap for something to slip through.
Inside the handoff
Pass trusted state, not the weight of the whole system
Once identity has traveled safely to the Order Specialist, the next question is how that sub-agent actually talks to the Order Management System sitting behind it. This is where Model Context Protocol, or MCP, comes in. MCP is a standard that lets a sub-agent safely call out to an external tool or system, in this case an OMS, and get back a structured response it can reason over. Rather than the agent needing bespoke, custom-built logic for every single backend it might ever touch, MCP gives it a consistent, predictable way to say "create this order," "cancel this order," or "check inventory for this SKU," and get a clean answer back.
Order Management on Salesforce is built on the core platform, which means it plays naturally with Service Cloud and can support requests like returns and fulfillment changes using the same data model your service team already works in. Wiring the Order Specialist to that system through an MCP endpoint, often via a standard HTTP callout or a lightweight Apex wrapper, keeps the connection tidy. The sub-agent doesn't need to understand every internal detail of how the OMS processes a cancellation. It just needs to know how to ask for one and how to interpret the response.
The Knowledge Specialist has a parallel but different relationship with data. Instead of calling out for transactional actions, it's grounded in Data Cloud's vector search, which indexes both structured records and unstructured content, things like PDFs, spec sheets, and support articles, so the agent can find relevant information without the entire catalog living inside its prompt. This is a meaningful distinction from the monolithic approach: instead of trying to preload every product detail into context "just in case," the Knowledge Specialist retrieves only what's relevant to the specific question being asked, when it's asked. Zero-copy data architecture takes this a step further, letting Data Cloud reach into external data lakes on demand rather than duplicating everything into Salesforce storage first. The result is a sub-agent that stays fast and current without ballooning in size as the product catalog grows.
Put together, this is the full map of how state, identity, and data move through the system: the router verifies and routes, session variables travel quietly behind the scenes, the Transaction Specialist reaches out through MCP for anything requiring backend action, and the Knowledge Specialist pulls grounded answers from Data Cloud without ever needing the raw catalog sitting in its lap.
Building It: A Step-by-Step Walkthrough
Let's make this concrete with a migration scenario. Say you're working with an existing monolithic support agent that's grown to handle twelve distinct customer intents, everything from "where's my package" to "cancel my subscription" to "what's your return policy." The agent works, technically, but it's slow, it forgets things mid-conversation, and the team maintaining it dreads every change request because nobody's entirely sure what will break.
Here's a practical path through that migration, step by step.
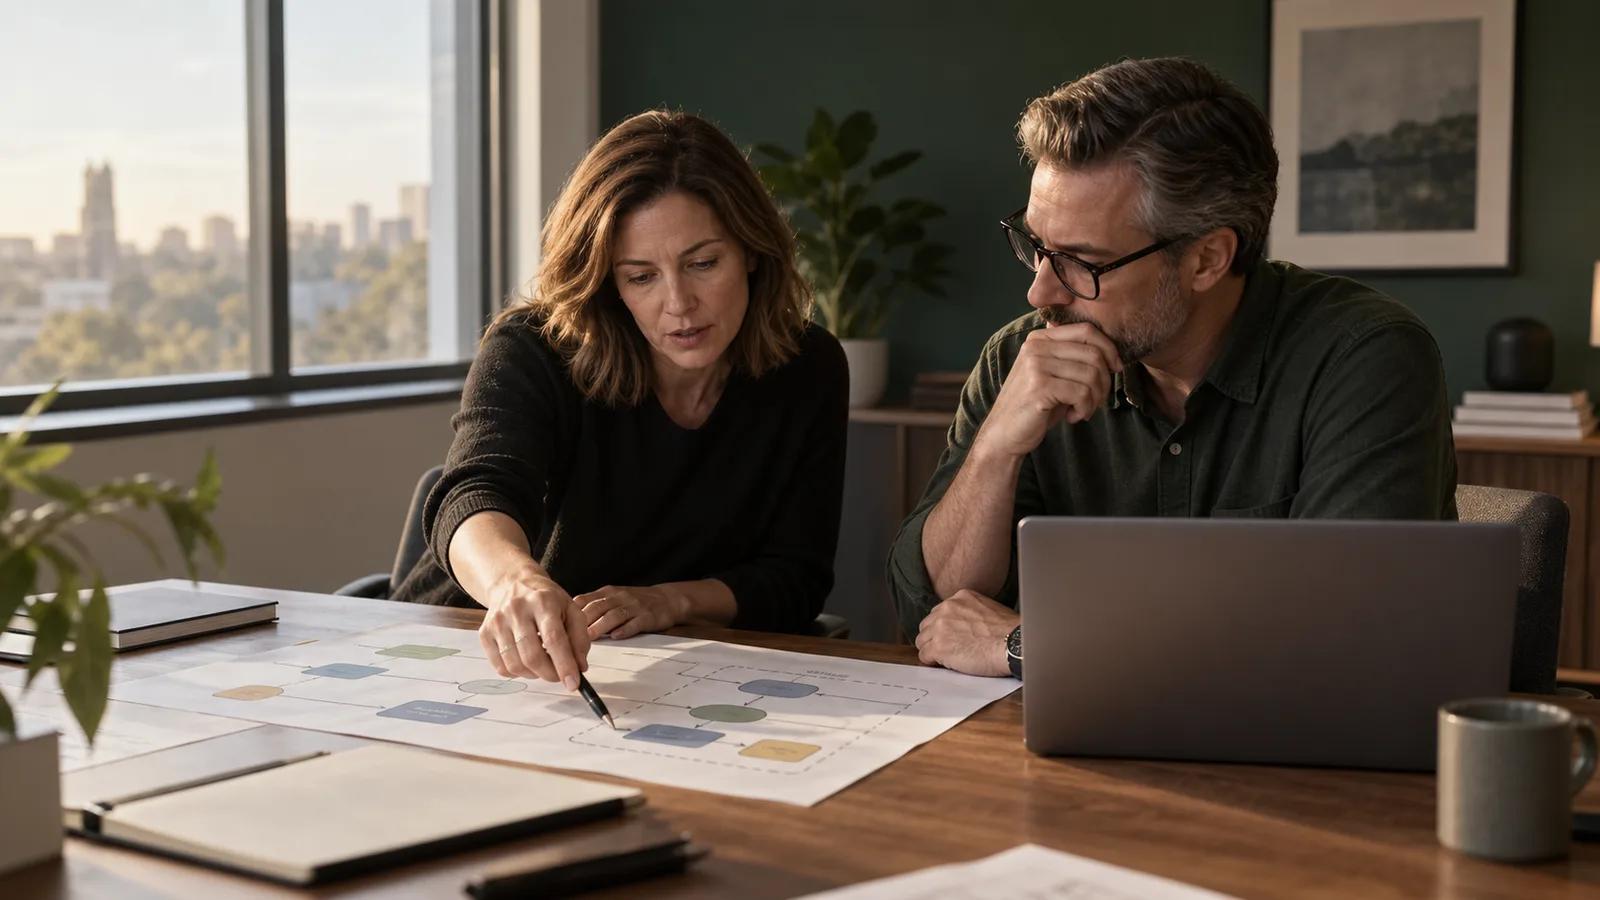
Audit the existing agent.
List every intent it currently handles, and sort each one into a category: identity or escalation, product knowledge, or transactional. In our example, this sorting reveals the twelve intents split roughly into three groups of four, which already hints at the shape the new architecture should take.
Separate the monolithic prompt into a routing topic and dedicated sub-agents.
The router keeps the identity confirmation, off-topic deflection, and escalation logic, since these apply to every conversation regardless of what the customer ultimately wants. A Product Catalog sub-agent takes over anything grounded in Data Cloud retrieval. An Order Fulfillment sub-agent takes over anything involving the OMS.
Build the primary routing agent inside Agent Builder
with basic intent topics. Keep its instructions short and focused on classification: "if the customer wants to know product details, route to Product Knowledge. If they want to check, change, or cancel an order, route to Order Fulfillment. If the request falls outside these areas, use the off-topic response."
Configure identity verification and off-topic guardrails at the orchestrator tier
only. This is the one piece of logic every sub-agent will rely on, so it belongs at the top, not duplicated three separate times.
Establish session variable parameters
for ContactId and SessionToken, so the router has a clean, consistent way to package verified identity before handing off a conversation.
Stand up the Order Specialist sub-agent
with scoped actions limited strictly to OMS-related functions: create, update, cancel, and inventory check. Nothing else lives in its prompt.
Wire the MCP connection
using a standard HTTP callout or an Apex wrapper, and implement it through an autolaunched Flow that receives the verified AccountId as input and dispatches the request to the external OMS endpoint. Flow is a good fit here because it already handles data, logic, and branching cleanly, and it gives you a visual, debuggable trail of exactly what happened on each transaction.
Connect Data Cloud vector search collections
to the Knowledge sub-agent, so product and policy questions get answered from grounded, current data rather than static prompt text that goes stale the moment a product spec changes.
Test the handoffs
using the Flow and Agent debug panels, watching specifically for whether session variables arrive intact at the sub-agent level, and whether the sub-agent picks up the conversation without asking the customer to repeat information already provided.
Enable Einstein Trust Layer data masking and Shield Event Monitoring
before going live, so no personal identifying information reaches the underlying model unmasked, and so your team has visibility into who's accessing what across the new, more distributed system.
Once this migration is complete, the payoff shows up almost immediately in conversation logs. In a well-executed version of this exact walkthrough, transactional conversation turns that used to carry roughly 6,800 tokens of accumulated context, instructions, schemas, and history all mixed together, drop to under 1,200 tokens per turn. That's not a marginal improvement. That's the difference between an agent that's straining against its limits and one with plenty of headroom left for a genuinely long, complicated conversation.
Where Multi-Agent Systems Go Wrong
Splitting an agent into pieces solves the bloat problem, but it introduces a new category of mistakes that don't exist in a single-agent design. It's worth naming the most common ones plainly, because most of them are easy to avoid once you know to look for them.
Recursive routing loops. This happens when the router hands a conversation to a sub-agent, that sub-agent decides it's not actually equipped to handle the request, and sends it back to the router, which then routes it right back to the same sub-agent. The customer ends up stuck in a loop, watching the same non-answer repeat itself. The fix is to make routing rules mutually exclusive and unambiguous at the router level, and to give every sub-agent a clear, final fallback action, like "escalate to human," rather than "send back to router," when it hits a request outside its scope.
Prompt leakage across session boundaries. This is a subtler problem, and it happens when instructions or context meant for one sub-agent accidentally bleed into another, usually because session variables or conversation history weren't scoped tightly enough during the handoff. A customer might ask the Order Specialist a product spec question, and instead of politely redirecting, the sub-agent tries to answer using half-remembered context it was never supposed to have. The fix is disciplined context isolation: each sub-agent's prompt space should contain only what it needs, and handoffs should pass structured variables, not raw conversation dumps.
Over-engineering sub-agents for simple declarative flows. Not every task needs a full sub-agent with its own reasoning layer. If a request is simple and deterministic, "what are your store hours," "what's your return window", it often doesn't need an LLM reasoning over it at all. A basic declarative Flow or a static response topic handles it faster and more predictably than routing it through a full sub-agent pass. Teams that reach for a sub-agent every time end up rebuilding the same bloat problem at a smaller scale, just spread across more pieces.
Ownership drift. This one is organizational rather than technical, but it matters just as much. Once you have four or five sub-agents instead of one, it's tempting for different teams to own different pieces without much coordination. That's fine until the router's classification logic changes and nobody tells the Order Specialist team that intent boundaries shifted. Keep a shared map of what each sub-agent owns and update it every time a routing rule changes, even if that feels like unnecessary paperwork in the moment.
Measuring Whether It Actually Worked
None of this architecture matters if you can't prove it's actually performing better than the monolith it replaced. Here are the metrics worth tracking, and what a healthy number looks like for each.
| Metric | What It Measures | Healthy Target |
|---|---|---|
| Token Consumption per Turn | How much prompt and context weight each conversational turn carries | Well below monolithic baseline; isolated sub-agent turns often run under 1,200 tokens |
| First Response Latency | Time to the agent's first reply after a user message | Under 1.5 seconds for router classification, under 3.0 seconds for transactional actions |
| Specialization Accuracy Rate | Percentage of queries correctly handled by the right domain-specific sub-agent | High and stable across both knowledge and transactional intents |
| Context Window Saturation Index | Percentage of a sub-agent's available working memory currently in use | Comfortably below capacity, even in long conversations |
| Escalation Deflection Ratio | Share of conversations resolved without needing a human handoff | Higher than the monolithic baseline, since specialists resolve more issues correctly on the first pass |
Token consumption per turn is the clearest signal that the architecture change actually worked, because it's the most direct measure of the bloat problem we started with. Compare a single-prompt monolithic turn against an isolated sub-agent turn handling the same type of request, and the gap tells you whether context isolation is doing its job.
First response latency matters because customers notice speed even when they can't articulate why something feels slow. A router classifying intent should respond almost instantly, since its job is narrow and its context is light. A Transaction Specialist calling out to an OMS through MCP will naturally take a bit longer, since it's waiting on a real backend system, but three seconds is a reasonable ceiling before customers start wondering if something's broken.
Specialization accuracy rate is where you catch the specialization gap we talked about earlier, if it's still lingering anywhere in the system. If the Order Specialist is getting simple product questions routed to it and fumbling them, or the Knowledge Specialist is getting transactional requests it can't act on, that's a signal the router's classification instructions need tightening, not that the sub-agents themselves are broken.
The Context Window Saturation Index tells you how much runway each sub-agent has left as conversations get longer and more detailed. A monolithic agent tends to climb toward saturation fast, since every domain's instructions are always present regardless of relevance. A properly isolated sub-agent should stay well under capacity, giving it plenty of room to hold onto genuine conversation history rather than losing earlier context to make space for standing instructions it doesn't need for this particular exchange.
Finally, the escalation deflection ratio is the business metric that ties all of this back to cost and customer experience. If specialists are actually more accurate and more responsive than the old monolithic design, fewer conversations should need a human agent to step in and finish the job. That's the number that shows up in a support team's headcount planning, not just in an engineering dashboard, and it's usually the number that convinces stakeholders the migration was worth the effort in the first place.
Turn the design into evidence
The architecture should become visible in the numbers
Put these five metrics together and you get a complete picture: how light each conversation is, how fast it moves, how accurately it's handled, how much memory room is left, and how often it resolves without human help. Track them before and after a migration like the one we walked through, and the case for breaking up the monolith stops being a matter of opinion. It becomes a number on a dashboard, and in most builds we've reviewed, it's not a small number. It's the difference between an agent that struggles under its own weight and one that gets faster, not slower, every time you add a new capability to it.
Read next
Three related 360Node insights
Architecture is only the beginning. These perspectives connect the data foundation, a controlled pilot and a sound platform decision.
Agentforce Pilot: From Prototype to Production Decision
A working Agentforce prototype is not yet a production case. The pilot should answer a harder question: does the use case create enough value, with acceptable behavior, permissions and operating effort, to justify running it day to day? That means defining the go/no-go criteria before the pilot starts — not after the demo looks promising.
Read article
The Data Foundation for AI: What Agentforce and Data 360 Actually Need
AI and Data 360 do not need every field to be perfect. They do need the important data to mean what teams think it means — with enough ownership, evidence and context to use it safely. The practical goal is not “clean all the data.” It is to make the critical data trustworthy enough for the process you want to improve.
Read article
Salesforce Standard or Custom? Choose for Fit, Not Ideology.
“Standard first” is useful guidance — until it becomes a rule that forces the business into the wrong process. Custom development can solve real problems — until every exception creates another lifecycle burden. The better decision is the simplest option that fits the requirement and that the team can still test, operate and change later.
Read article